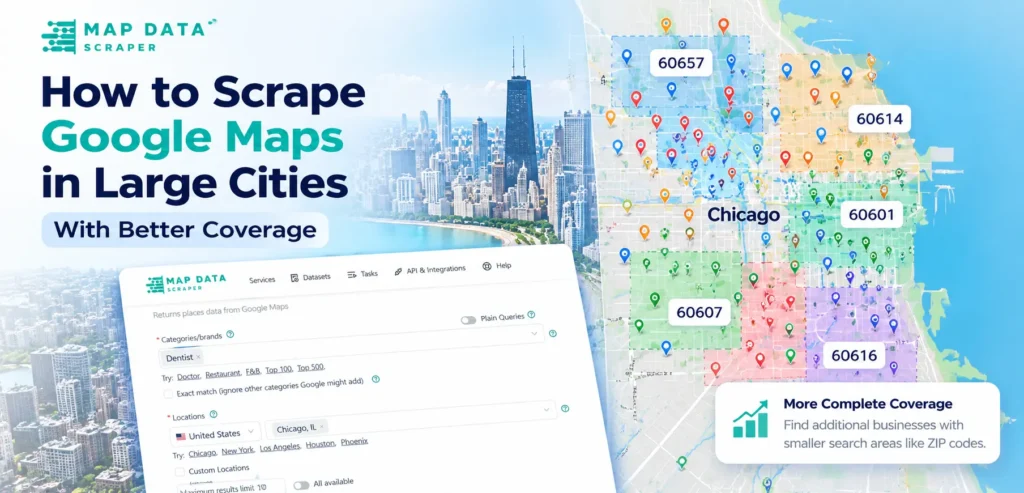
To scrape Google Maps in large cities with better coverage, one broad city query is rarely enough. Search results are ranked, dense markets contain more listings than a single query may surface, and postal areas do not always match legal city boundaries. A stronger workflow begins with a baseline city search, repeats the same business category across smaller supported areas such as ZIP or postal codes, then combines and deduplicates the exports. This guide shows how to plan that process in MapDataScraper, retain valid branch locations, filter out-of-area records, and measure whether each additional search contributed useful new businesses without claiming that the final dataset contains every listing.
Test the method with one city and one category
Map Data Scraper
Choose a business category, run one broad city query, and save the result as your baseline before dividing the market into smaller search areas.
Start Scraping NowQuick answer
To improve Google Maps scraping coverage in a large city, run one broad city query as a baseline, repeat the same category across smaller supported areas such as ZIP or postal codes, combine the exports, and deduplicate by Place ID or Google ID. Then filter records against the intended boundary and measure how many new unique businesses each additional search contributed.
Why One Broad City Query May Miss Relevant Businesses
A broad search such as:
Dentists in Chicago, Illinois
is a useful starting point. However, it should not automatically be treated as a complete inventory of every dentist operating in Chicago.
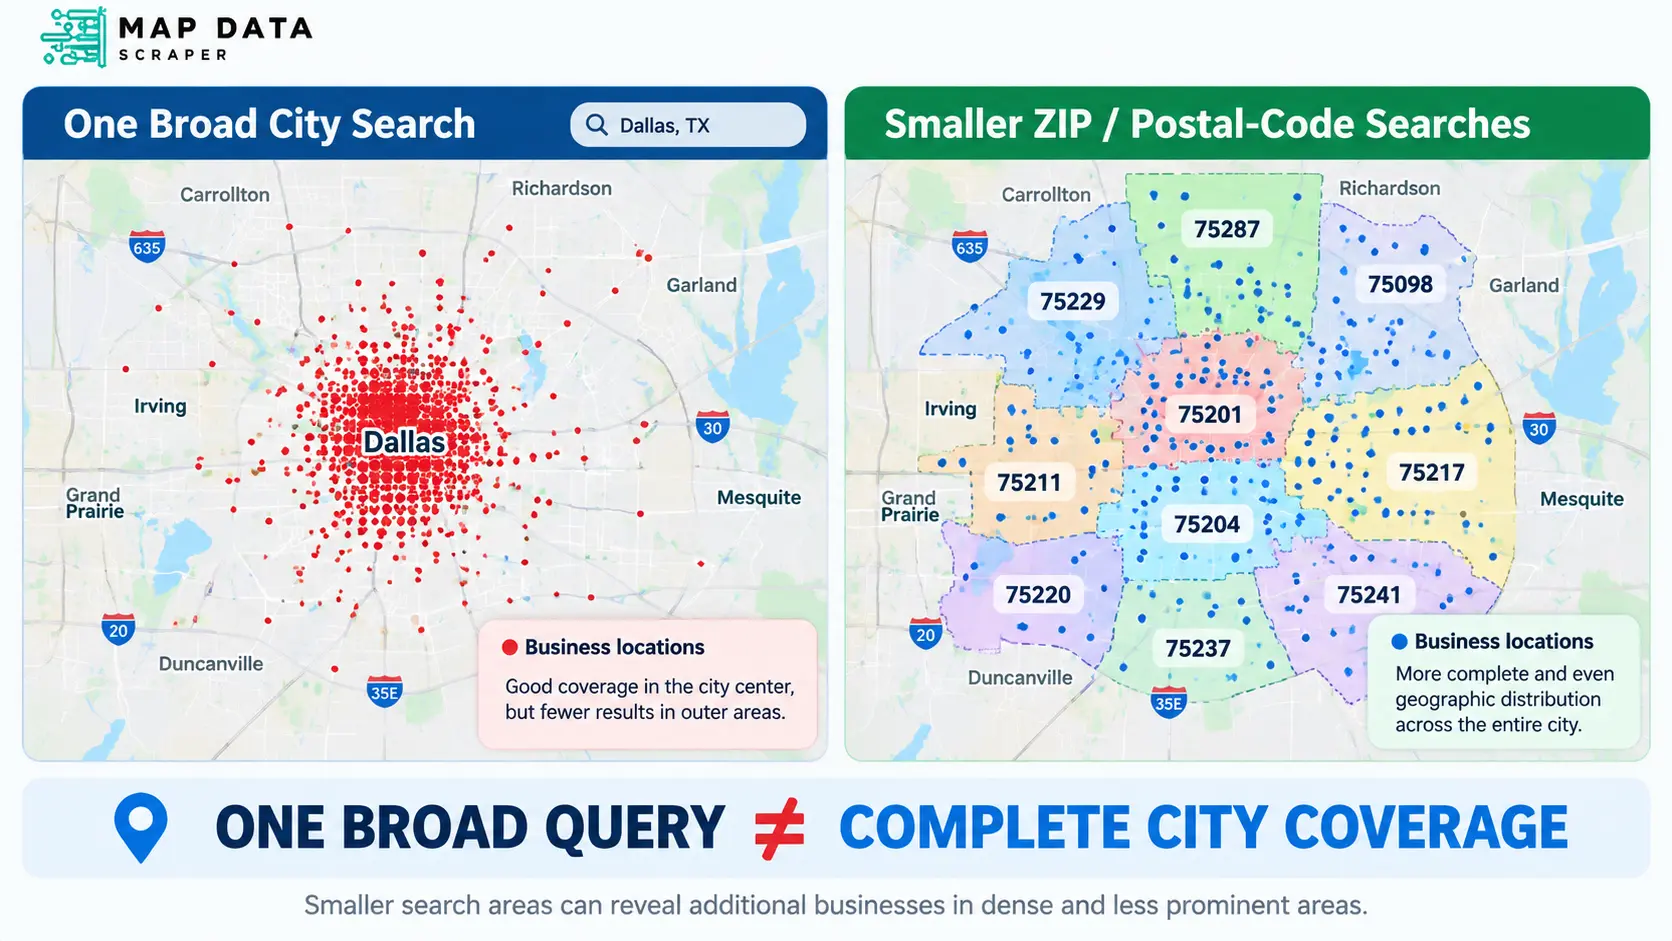
Location-search systems rank businesses according to relevance, prominence, geography, category matching, and other factors. Google’s own Places search documentation explains that returned places are ordered by perceived relevance, that identical searches are not guaranteed to return a perfectly consistent list, and that search responses have result limits.
That does not mean the broad query is useless. It means the result represents the businesses surfaced for that search—not proof that no other relevant businesses exist.
Increasing the maximum-results setting can allow a task to return more records, but a task-level maximum is different from exhaustive coverage of every underlying search area. In a dense market, smaller location searches can surface businesses that were not prominent enough to appear in the broad city result.
This distinction is central:
Better coverage is a collection-design problem, not only a result-limit problem.
The goal is not to promise that every business will be found. The goal is to use a consistent process that reduces likely gaps and documents what the dataset actually includes.
Define the Business Category and Geographic Boundary First
Before creating multiple searches, decide exactly what belongs in the dataset.
A collection plan should answer four questions:
| Decision | Example | Why it matters |
|---|---|---|
| Business type | Dentist | Prevents unrelated categories from entering the dataset |
| Geographic unit | Chicago city limits | Defines which locations belong in the final file |
| Business status | Operational listings only | Prevents known closed locations from affecting the count |
| Collection date | November 2026 | Makes the dataset reproducible and easier to refresh |
Keep the category consistent
Do not search for:
- dentists in one ZIP code;
- dental clinics in another;
- orthodontists in another;
- cosmetic dentistry in another;
and then treat the combined results as one consistent dataset without documenting the differences.
Different search terms can represent different business populations.
For a clean comparison, begin with one defined category or query and use it consistently across every search area. Separate related categories can be collected in additional passes and labeled clearly.
Define whether the project uses city or metro boundaries
“Chicago” can mean:
- the legal city;
- the postal city;
- the broader metro area;
- nearby municipalities commonly associated with Chicago.
Those are not interchangeable.
A city-proper project should filter returned locations against the intended city boundary. A metro project should explicitly list the municipalities, counties, or other geographic units included.
Treat ZIP codes as collection units not exact city boundaries
ZIP codes are designed for mail delivery rather than municipal geography. The U.S. Census Bureau explains that ZIP codes are point-based postal constructs, while ZIP Code Tabulation Areas are generalized statistical representations. A postal city name can also differ from the legal municipality where an address is physically located.
Therefore:
Searching Chicago ZIP codes can improve collection coverage, but the final rows still need a city, address, or coordinate check when strict city limits matter.
This prevents a larger ZIP-based collection from quietly becoming a mixed Chicago-and-suburb dataset.
Run a Broad City Query as the Baseline
The first collection should use the broadest search that still matches the project.
For the dentist example:
Category or query:Dentist
Location:Chicago, Illinois, United States
Filters:
Operational businesses only, when appropriate
Export format:
CSV or XLSX for spreadsheet review
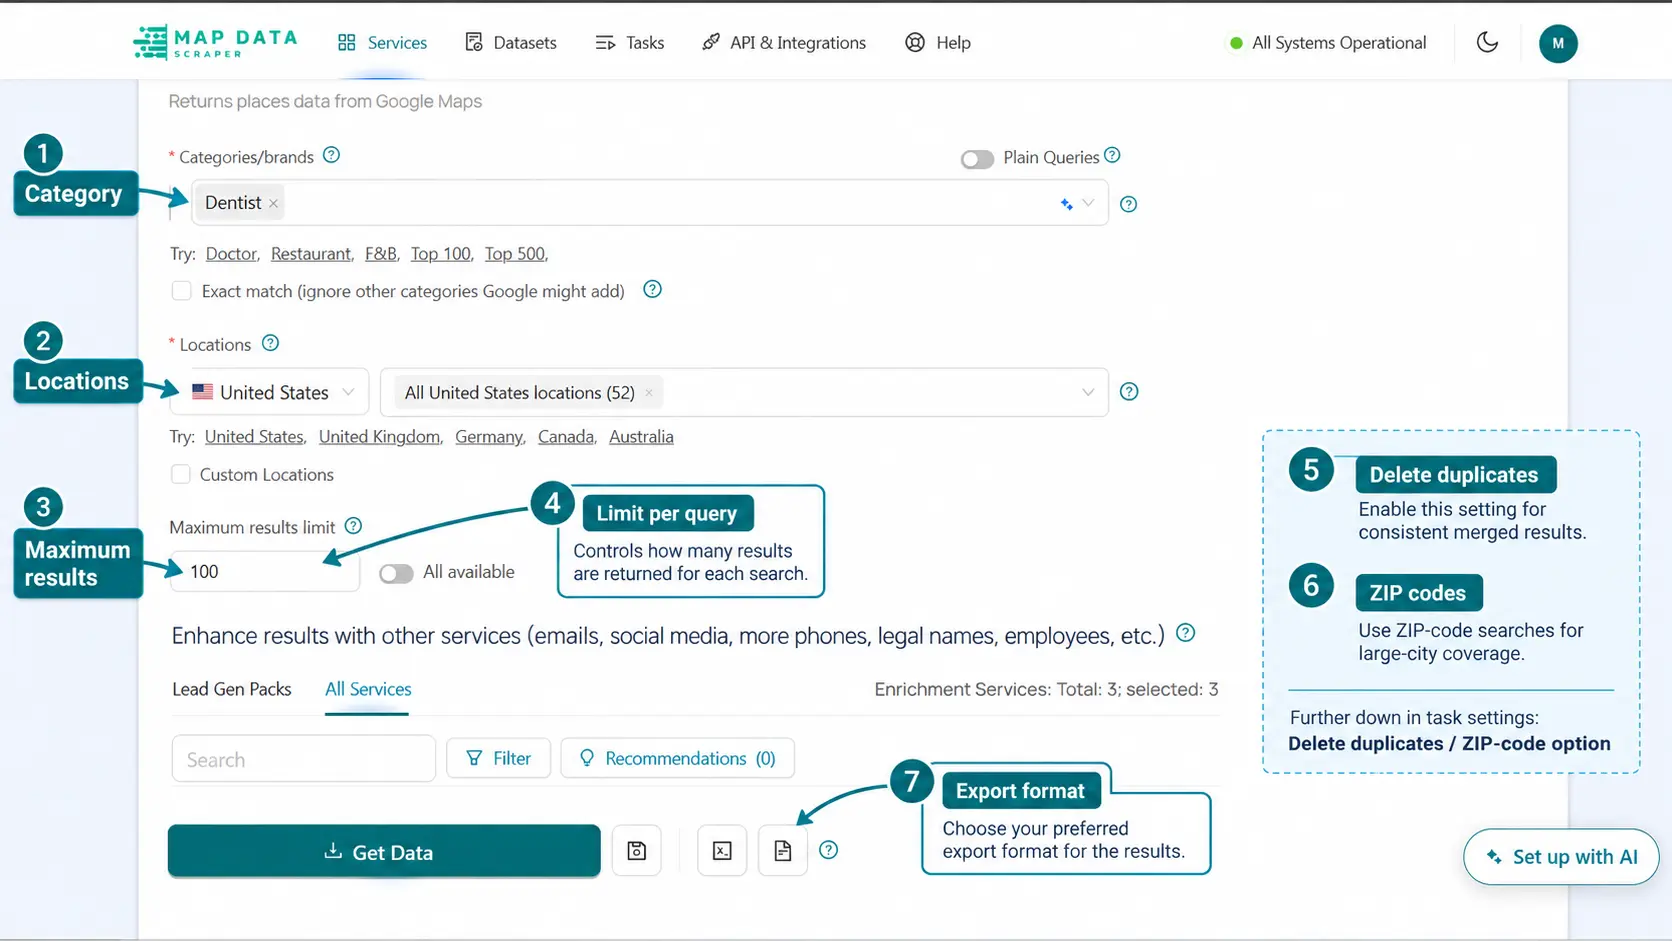
MapDataScraper’s current workflow supports categories or brands, one or multiple locations, custom locations such as a city or ZIP code, maximum-results controls, per-query settings, filters, duplicate removal, ZIP-code use, and exports including XLSX, CSV, JSON, and Parquet.
Save this first export separately.
Suggested filename:
dentists-chicago-broad-city-baseline.xlsx
The baseline gives you:
- an initial business count;
- the first set of Place IDs or Google IDs;
- an initial map distribution;
- a comparison point for later searches.
Do not clean the baseline by deleting legitimate branches simply because they share a brand name. A dental chain with several physical offices can have several valid location records.
Record the baseline settings
Keep a simple collection log:
| Setting | Baseline value |
|---|---|
| Category/query | Dentist |
| Location | Chicago, Illinois |
| Operational filter | Yes or no |
| Language | Selected task language |
| Maximum results | Task setting used |
| Per-query limit | Task setting used |
| Duplicate removal | Yes or no |
| Collection date | Actual task date |
| Export format | XLSX, CSV, JSON, or Parquet |
This log prevents the later ZIP-code searches from using different settings accidentally.
Save the broad query before expanding the search
Map Data Scraper
The baseline makes it possible to measure whether smaller-area searches actually added new businesses instead of simply producing more duplicate rows.
Run the Baseline SearchDivide the City Into Smaller Search Areas
After completing the baseline, repeat the same category across smaller supported areas.
MapDataScraper currently supports custom locations using a city or ZIP code with a country, and its advanced parameters include ZIP-code use, per-query limits, filters, and duplicate removal.
The important rule is consistency:
Use the same business definition, filters, language, and collection period across every area.
ZIP or Postal Codes :
ZIP or postal codes are often the most practical way to split a large city into repeatable collection units.
For example:
| Query | Location |
|---|---|
| Dentist | Chicago ZIP 60601 |
| Dentist | Chicago ZIP 60602 |
| Dentist | Chicago ZIP 60603 |
| Dentist | Chicago ZIP 60604 |
Continue with the ZIP codes included in the project scope.
Keep an additional source_area column in the combined dataset. That column should record which ZIP-code query returned each row.
This makes it possible to:
- trace each result back to its search;
- find overlap between areas;
- calculate duplicates;
- identify areas that produced few or no businesses;
- rerun specific areas later.
Remember that a ZIP-code result can include locations outside a strict city boundary. Perform geographic QA after combining the files.
Neighborhoods or Districts
Named neighborhoods can be useful when:
- the current MapDataScraper interface resolves the location correctly;
- local businesses commonly identify with that neighborhood;
- ZIP codes cover areas that are too broad or cross important boundaries.
Test several known businesses before relying on a neighborhood query at scale.
If the location resolves inconsistently, use a supported ZIP or postal-code structure instead of assuming the neighborhood name produces a precise boundary.
Nearby Municipalities for Metro Research
If the research question concerns a metropolitan market rather than city proper, create a documented list of included municipalities.
For example, a Chicago metro project might include Chicago plus selected surrounding cities or suburbs.
Do not add nearby areas informally during the collection. Define them before the task begins and keep their records labeled separately.
Practical search plan
| Search level | Purpose |
|---|---|
| Broad city query | Establish the baseline |
| ZIP/postal-code searches | Improve local geographic coverage |
| Tested neighborhood searches | Investigate specific dense or missing areas |
| Nearby municipalities | Expand only when the project is explicitly metro-level |
Combine, Filter, and Deduplicate the Results
After the smaller-area tasks finish, combine their exports into one working file.
Add or preserve these columns:
- business name;
- Place ID;
- Google ID;
- full address;
- city;
- postal code;
- latitude;
- longitude;
- category;
- business status;
- source query;
- source area;
- collection date.
MapDataScraper supports spreadsheet and structured-data exports including XLSX, CSV, JSON, and Parquet, making it possible to combine and review the results outside the collection interface.
Use Place ID or Google ID first
Google describes Place ID as an identifier for a place in Google Maps and the Places database. Google also notes that a place can sometimes have multiple IDs and that IDs may change over time, so Place ID is a strong operational identifier rather than a permanent legal-company identifier.
For one collection project, use this review order:
| Priority | Duplicate check | Recommended action |
|---|---|---|
| 1 | Same Place ID or Google ID | Treat as the same place record |
| 2 | Same Maps URL or exact location identifier | Review as a probable repeat |
| 3 | Same normalized name and address | Review manually |
| 4 | Same name but different address | Usually retain as separate locations |
| 5 | Same domain but different Place IDs | Retain unless other evidence shows a duplicate |
Do not deduplicate primarily by business name.
A chain may have many valid branches with:
- the same brand name;
- the same website domain;
- similar categories;
- different addresses and Place IDs.
Removing those records would reduce the dataset’s actual location coverage.
Keep the source-area history
Suppose one dentist appears in:
- the broad Chicago query;
- ZIP 60601;
- ZIP 60602.
The final dataset should keep one location row, but the working file should preserve that the place was found in three searches.
A useful field could be:
source_areas = Chicago baseline; 60601; 60602
This helps you understand overlap and rerun the collection later.
Filter the final geography
After deduplication, check whether every record belongs inside the intended geography.
Possible review fields include:
- city;
- postal code;
- latitude and longitude;
- formatted address;
- source area.
For strict city-level research, remove or separately label businesses that fall outside the city boundary.
Do not delete them silently. They may still be valuable for a broader metro analysis.
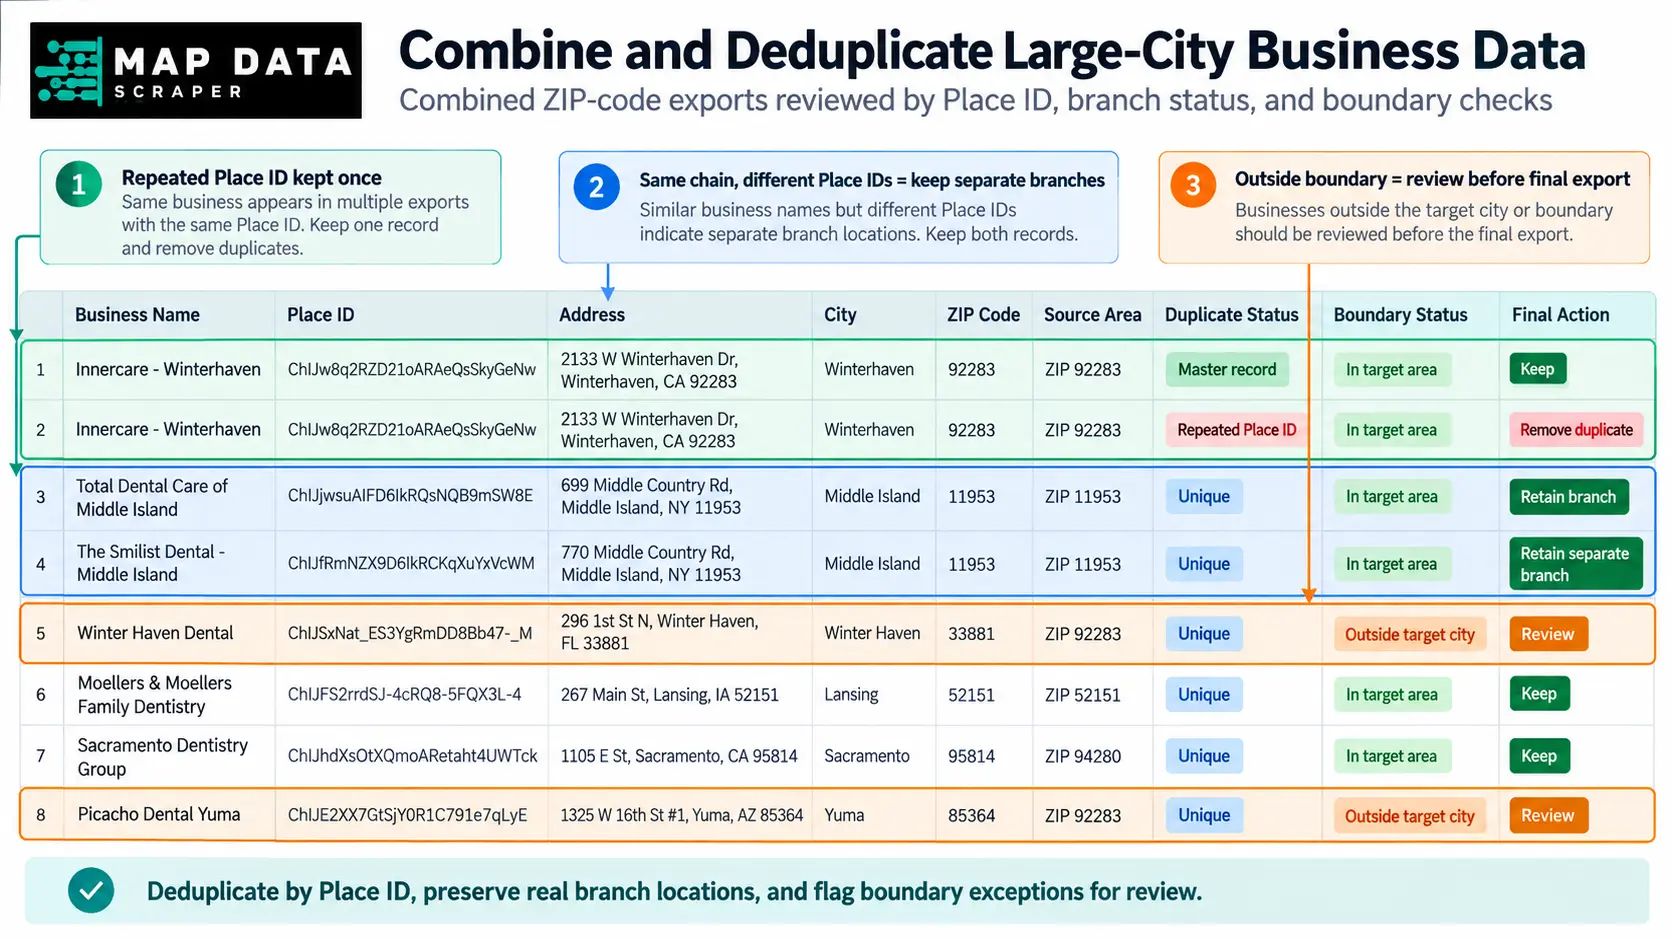
Clean the combined dataset before using it
Map Data Scraper
Preserve the source search, remove repeated place records, review boundary exceptions, and normalize fields before sending the data into a lead list, CRM, map, or research model.
Review the Data-Cleaning WorkflowMeasure Whether the Additional Searches Improved Coverage
More raw rows do not automatically mean better coverage.
ZIP-code searches can produce:
- genuinely new businesses;
- businesses already found in the baseline;
- the same business returned by several overlapping areas;
- records outside the target boundary;
- related but out-of-scope categories.
Measure what changed after combining and cleaning the files.
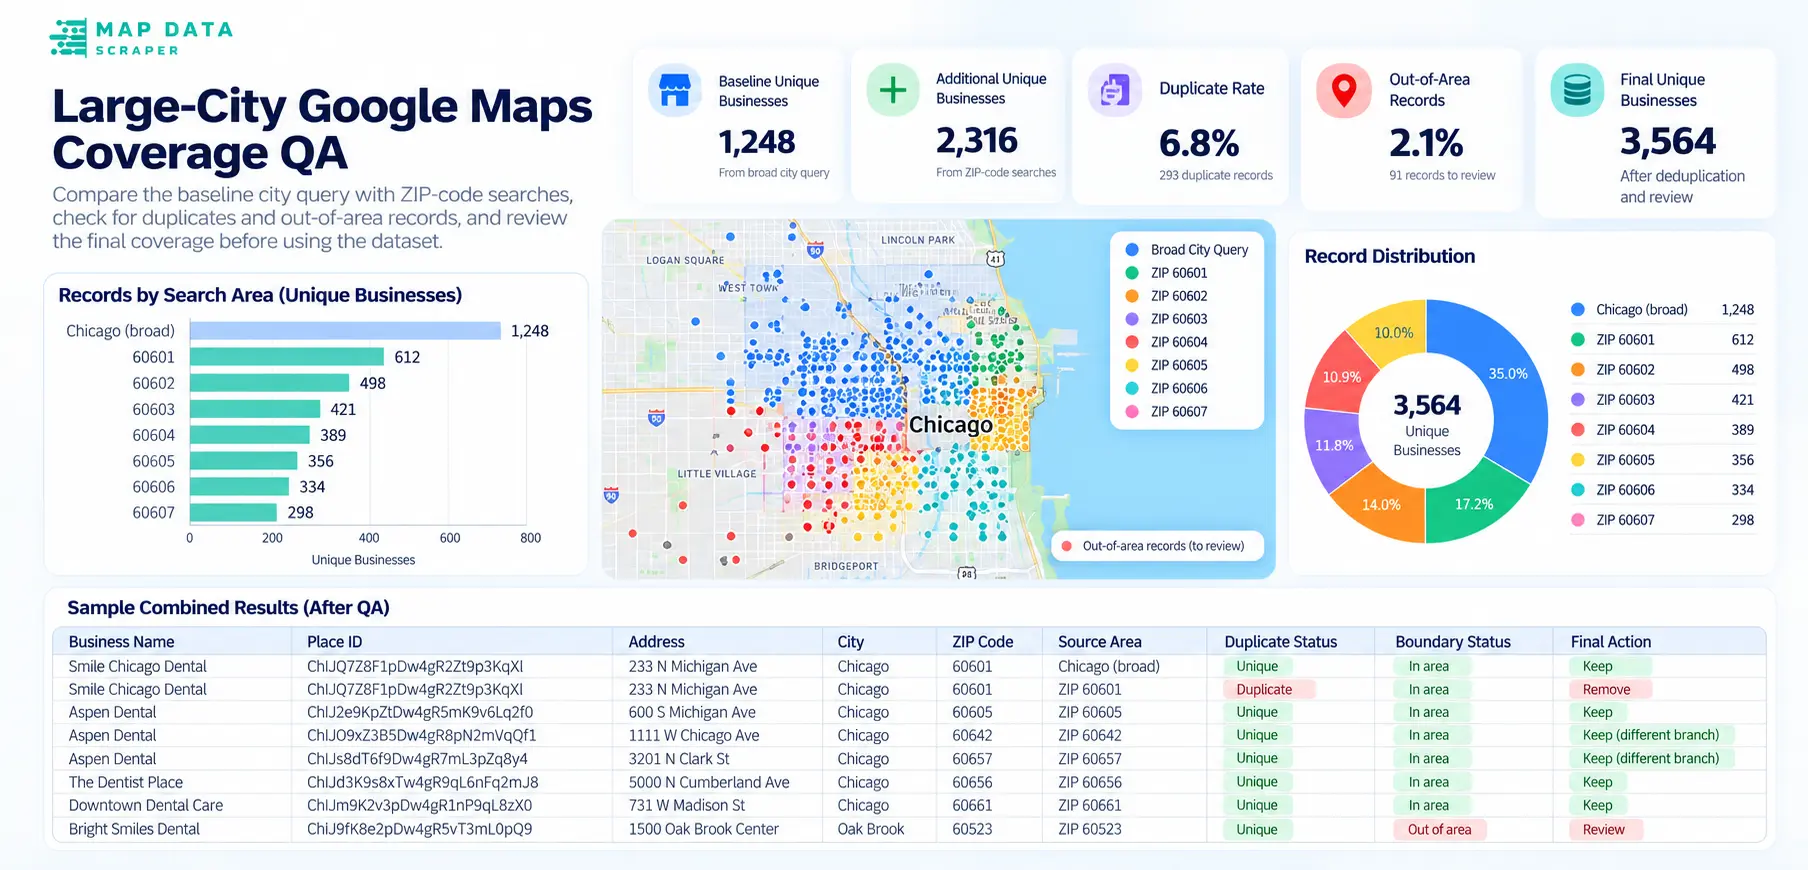
Core coverage metrics
| Metric | Calculation | What it tells you |
|---|---|---|
| Baseline unique places | Unique Place IDs from the city query | Starting point |
| Additional unique places | New Place IDs found only in smaller-area searches | Incremental coverage |
| Duplicate rate | Repeated rows ÷ total raw rows | Search-area overlap |
| Out-of-area rate | Records outside the target ÷ total unique records | Boundary leakage |
| Coverage gain | Additional unique places ÷ baseline unique places | Relative contribution of smaller searches |
| Records by search area | Unique records associated with each area | Geographic distribution |
| Missing known businesses | Expected businesses absent from the dataset | Possible coverage gap |
Review diminishing returns
If the first ten ZIP-code searches contribute many new unique businesses and the next ten contribute very few, the collection may be approaching diminishing returns.
That does not prove completeness.
It helps determine whether additional searches are still producing enough value to justify the cost and processing work.
Check the map distribution
Plotting the final latitude and longitude fields can reveal:
- unexpectedly empty districts;
- heavy clustering around the city center;
- records outside the intended area;
- ZIP codes producing no results;
- areas that may need another query.
MapDataScraper currently exports location fields that can be reviewed in spreadsheets or mapping and BI tools.
Document the final method
A publishable or reusable dataset should record:
- business category;
- included geography;
- excluded geography;
- broad baseline query;
- ZIP or postal codes searched;
- other location units used;
- filters;
- task settings;
- collection dates;
- unique-record key;
- boundary-check method;
- known limitations.
That documentation is what makes the dataset reproducible.
The claim should be:
The method improved coverage and added new unique business records.
Not:
The dataset contains every business in the city.
Better large city coverage starts with a better search plan, not simply a higher result setting.
Use one broad query to establish the baseline, repeat the same category across smaller supported areas, retain the source of every row, and measure what the additional searches actually contributed. The result is a more systematic dataset whose scope and limitations are clear.
FAQ
Most frequent questions and answers
No. A task-level maximum controls how many results the task may return, but it does not prove that every relevant business was surfaced for each search. Better coverage usually requires a consistent category, smaller search areas, combined exports, deduplication, and geographic QA.
ZIP or postal codes are often easier to repeat consistently because MapDataScraper currently supports custom ZIP-based locations. Neighborhoods can be useful, but test whether the current interface resolves them accurately before relying on them for a full project. Remember that ZIP codes may cross legal city boundaries.
Use Place ID or Google ID as the first duplicate key. Records with the same name but different Place IDs and addresses may be legitimate branches. Review them as separate locations unless other evidence shows they represent the same place.
No collection method should promise that every business will be returned. Listings can be missing, categorized differently, ranked too low to appear, recently changed, or outside the query’s interpretation. The responsible goal is to improve and document coverage rather than claim exhaustive completeness.
Record the category, geographic scope, locations searched, filters, maximum-results settings, per-query settings, collection dates, duplicate key, boundary rules, and known limitations. Keep the broad baseline separate so later refreshes can follow the same method.
Build a better-documented city dataset
Map Data Scraper
Start with one category and one large city. Compare the broad city result with smaller-area searches before scaling the same process to more markets.
Start With MapDataScraper